Models#Coding agent#Model inference
GLM-5.3-Highspeed shows up in Zcode at 490 tokens/s
Zhipu's unannounced GLM-5.3-Highspeed is rolling out to random Zcode 3.15.1 subscribers; one user measured 490 tokens/s. No official numbers or pricing yet.
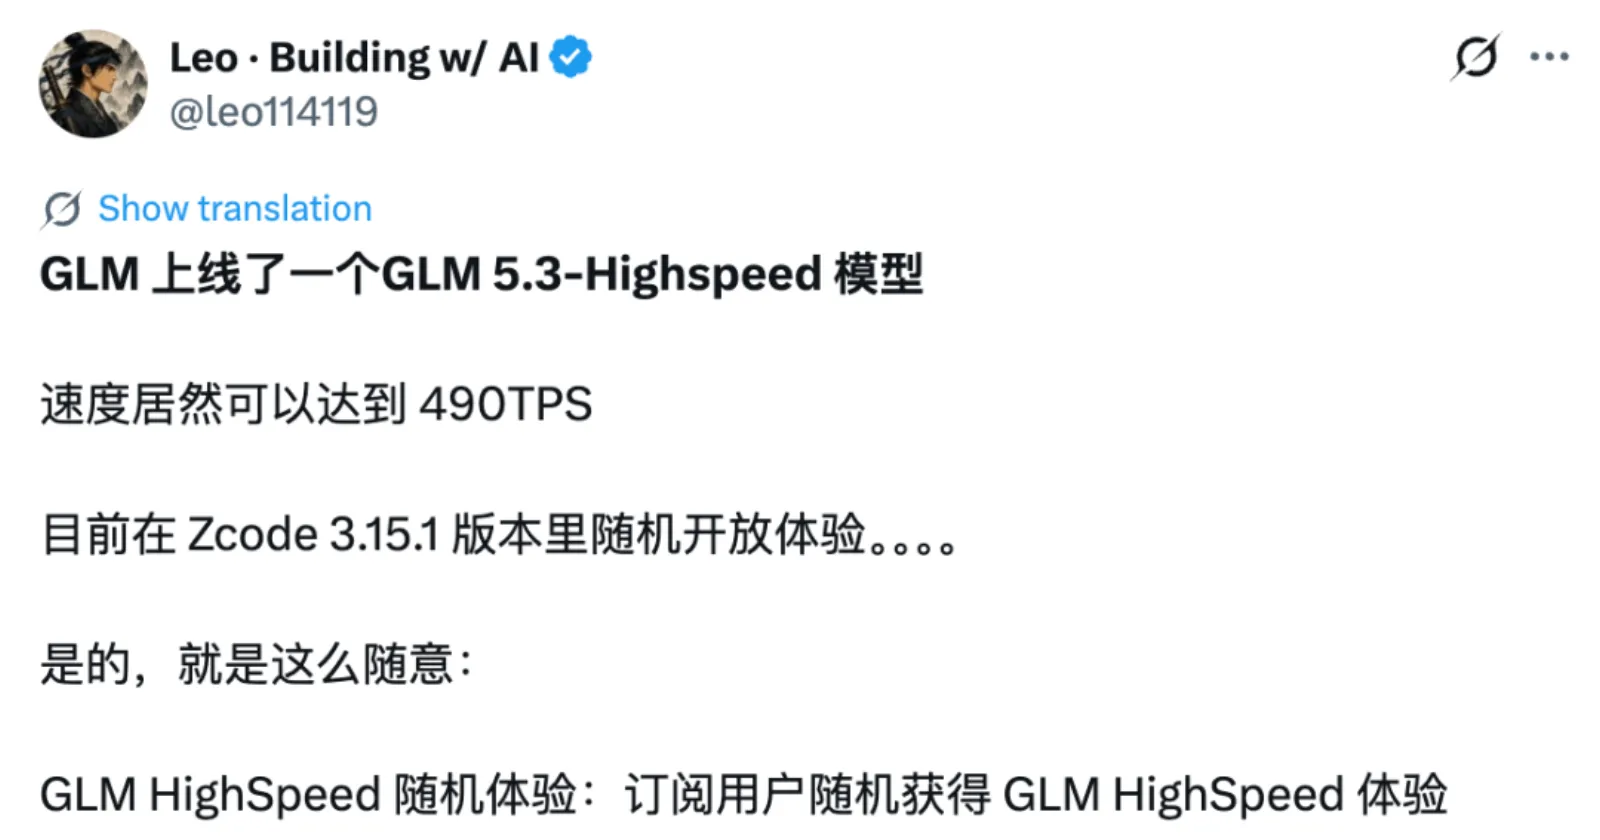
On October 12, QbitAI reported that Zhipu has an unannounced model, GLM-5.3-Highspeed, live inside Zcode 3.15.1 and being handed out to random subscribers. A user named Leo (@leo114119) posted a screenshot showing 490 tokens/s of output — at that rate, generating 10,000 tokens takes about 20 seconds. Zhipu has published nothing: the model isn’t in Z.ai’s developer docs as of October 12.
Key points
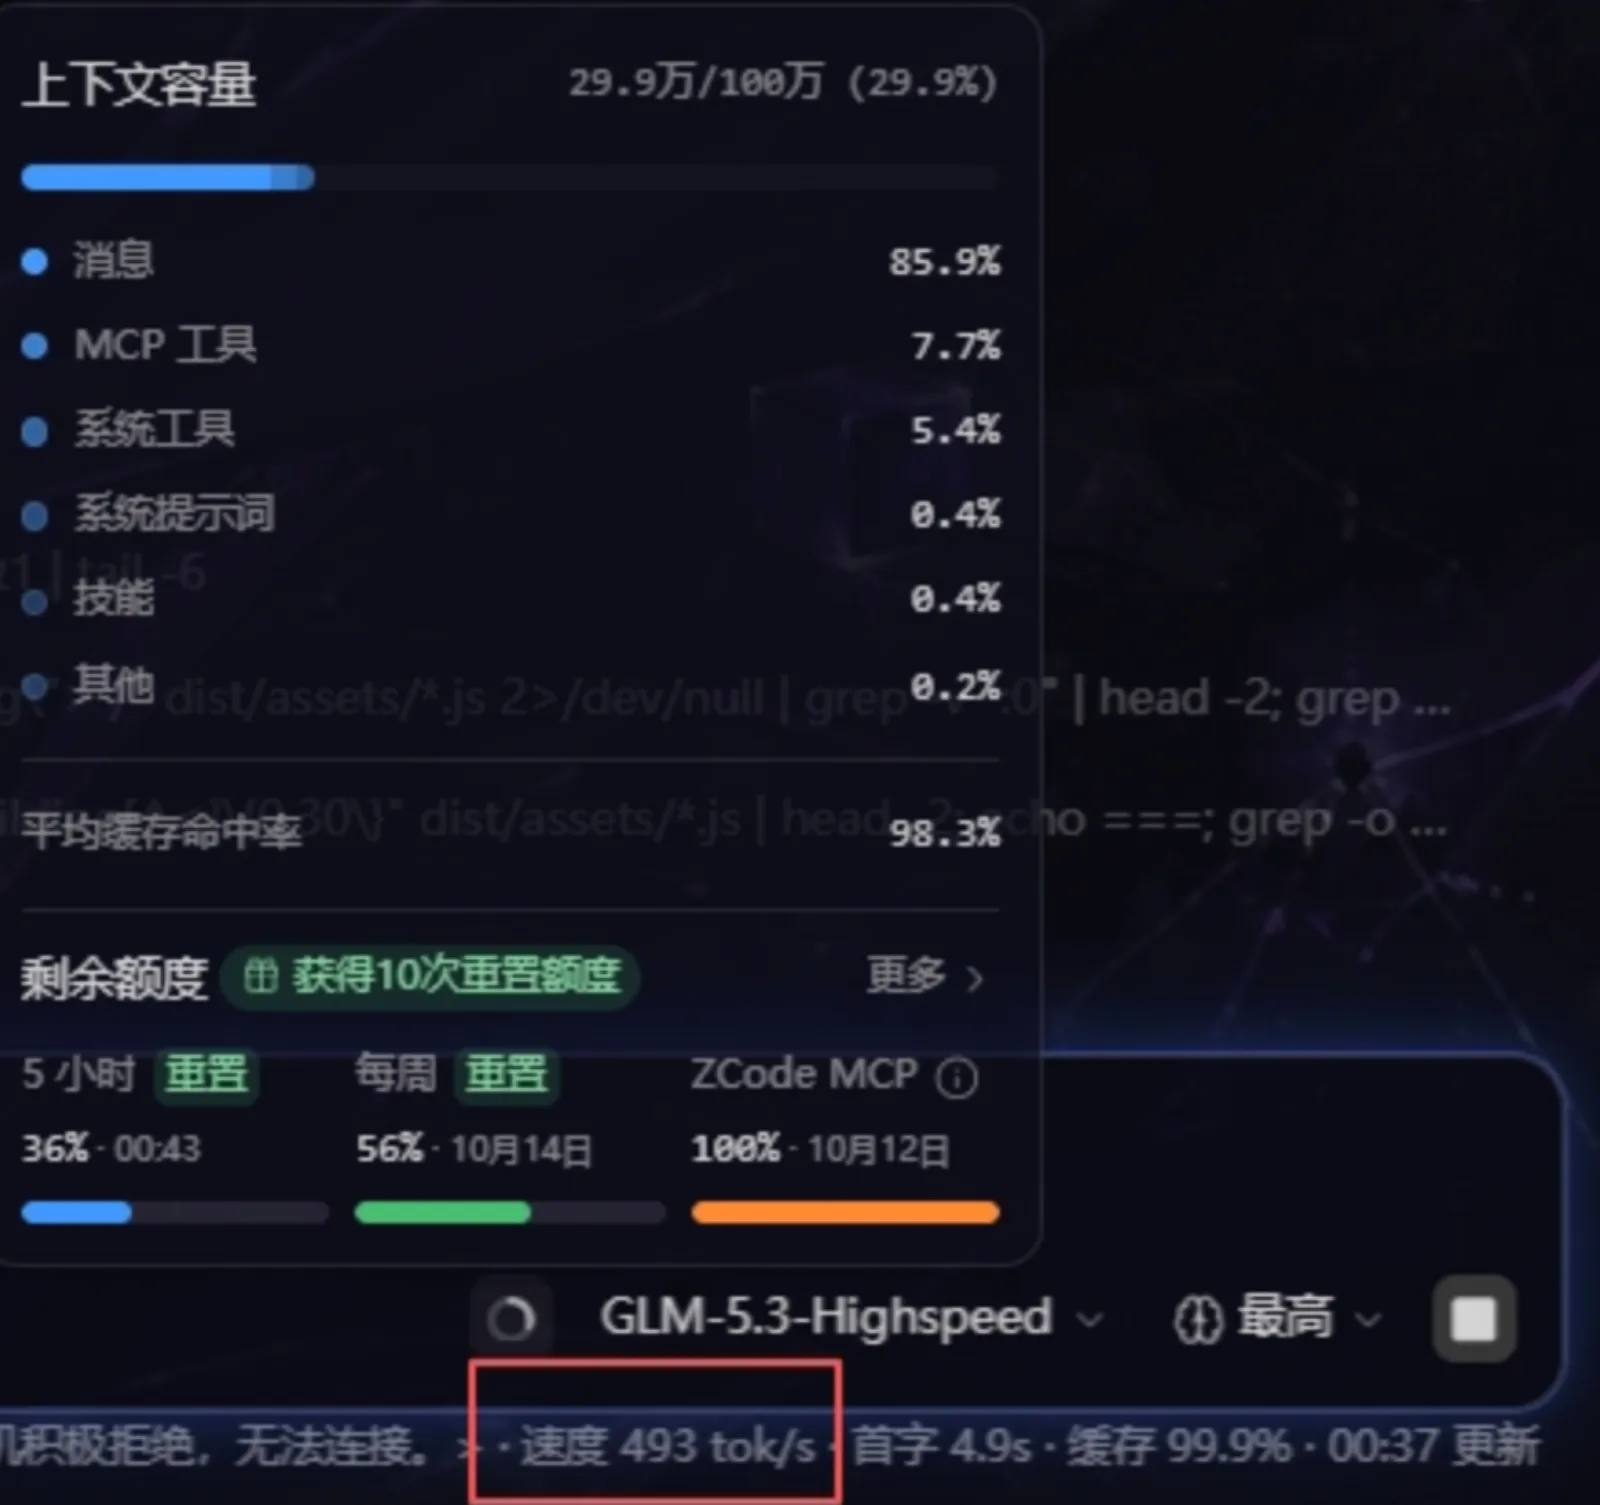
- 490 tokens/s, from one screenshot: the figure comes from @leo114119’s X post and a Zcode status bar (493 tok/s, 99.9% cache hit) making the rounds since. Zhipu hasn’t confirmed it, and nobody independent has reproduced it.
- Random rollout, no opt-in: the phrasing in @leo114119’s post — “random GLM HighSpeed trial: subscribers are granted access by lottery” — and even QbitAI’s author didn’t get in.
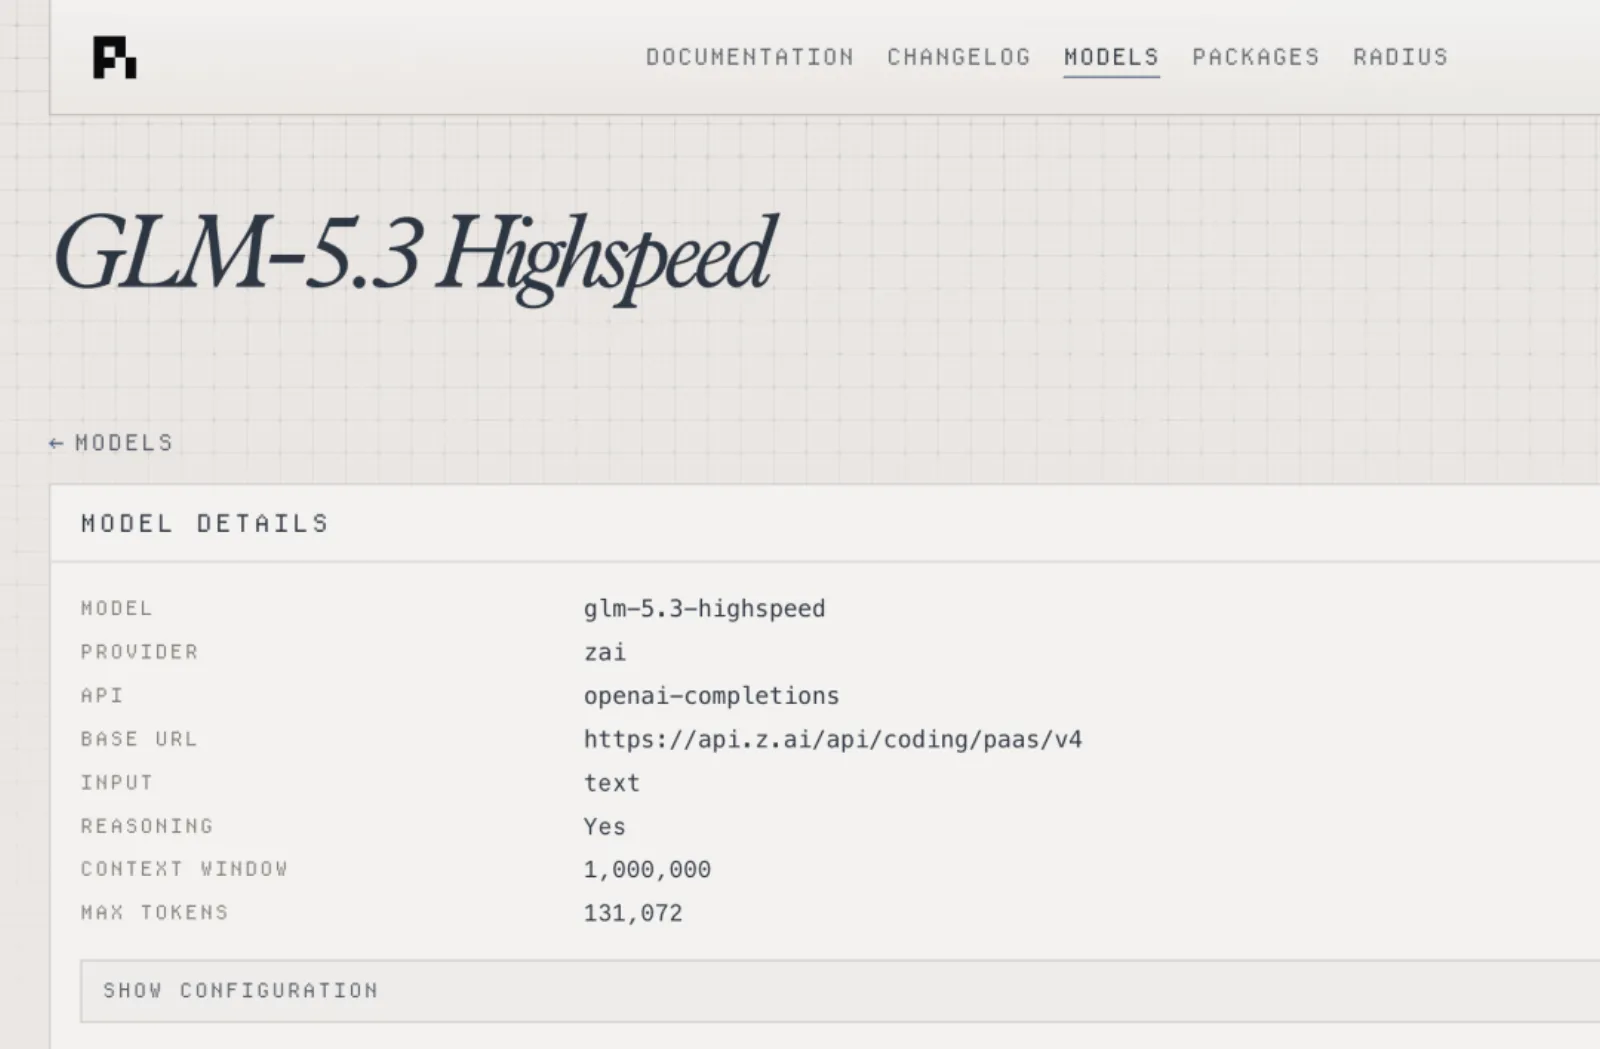
- Specs already public in a third-party catalog: Pi’s model directory lists glm-5.3-highspeed with a 1,000,000-token context window, 131,072 max output tokens, off/low/high/max reasoning levels, and a $0 price.
Background
Speed has been Zhipu’s most visible lane all year. GLM-5.3 landed in August with a coding focus; September’s GLM-5.3-FlashX pushed peak output to 200 tokens/s, while Artificial Analysis (cited by QbitAI) measures GLM-5.3-Flash at roughly 60 tokens/s on the Z.ai API. Further back, QbitAI recalls GLM-5.1-highspeed hitting 400 tokens/s in May, which was called the fastest API output available at the time. A faster variant every few months has become the company’s rhythm.
The stealth-model thread matters too. In early September an anonymous model, Omen Alpha, appeared in OpenCode; the UI briefly showed a zhipu/omen-alpha label, and the community has treated it as a Zhipu GLM-5-family model since. We’ve covered this playbook before — Space Bunny topping the OpenRouter and OpenCode usage charts — and rivals are moving the same direction: MiniMax shipped an M3.1-Flash preview in late September with 1M context in a Flash tier and, likewise, no pricing.
The facts
Specs as listed in Pi’s model catalog, checked October 12:
| Item | Value |
|---|---|
| Model name | glm-5.3-highspeed |
| Provider | zai (api.z.ai/api/coding/paas/v4) |
| Context | 1,000,000 tokens |
| Max output | 131,072 tokens |
| Reasoning | off / low / high / max |
| Listed price | $0; official pricing unpublished |
Speed comparisons, with each figure’s source and date:
| Model | Output speed | Source |
|---|---|---|
| GLM-5.3-Flash | ~60 tokens/s | Artificial Analysis, via QbitAI |
| GLM-5.3-FlashX | up to 200 tokens/s | QbitAI, Sep 2026 |
| GLM-5.1-highspeed | 400 tokens/s | QbitAI retrospective, unverified |
| GLM-5.3-Highspeed | 490 tokens/s | @leo114119 screenshot, Oct 12, 2026 |
Availability: random gray release to Zcode 3.15.1 subscribers with no opt-in; visible in Pi’s harness model list; Z.ai’s official docs (checked October 12) still list only GLM-5.3 and GLM-5.3-Flash. Pi’s catalog also shows the model served from Z.ai’s coding endpoints, international and China (zai-coding-cn) alike, under the /api/coding/ base URL — consistent with a Coding Plan perk rather than a general-purpose API model. The Zcode screenshot itself adds corroborating detail: a 98.3% average cache hit and 299k of 1M context used, matching the catalog’s window.
What others say
Leo’s own framing of the rollout: “yes, it’s that arbitrary” — a lottery, not a request queue. On r/ZaiGLM, IsseyShiitake connected the dots to Omen Alpha: the rumor mill has that stealth model at “nearly identical performance to 5.3-Flash but three times the tokens per second,” which matches Highspeed’s profile. Others temper the excitement — Sad_Recording_1290 points to OpenAI’s fast mode as the likely template: 50% more speed at double the per-token price, so a production Highspeed probably arrives with its own billing tier or quota. IsseyShiitake also recalls Z.ai’s pricing page promising the priciest plans early access to new models — if that memory is right, the lottery isn’t purely luck. As for Omen Alpha itself, the community testing QbitAI relays reads: fast, thinks for a long time, and the results hold up. Another user was blunter — GLM 5.3 “is a bit slow,” so “if it has good speeds that would be crazy.” No independent benchmark exists yet; every speed figure in circulation is a personal screenshot.
Our take
If 490 tokens/s holds up, the wait that dominates coding-agent sessions shrinks by an order of magnitude: 10,000 generated tokens drop from roughly three minutes on Flash to twenty seconds, and “time watching the model think” stops being the bottleneck on long tasks. That’s a real difference for anyone running agents daily, and it makes speed — not just context length — the next axis coding plans compete on. But keep the ledger honest: the number is one screenshot, unconfirmed by Zhipu and unreproduced elsewhere; the rollout is a lottery most subscribers haven’t won; and pricing is unpublished, so how much “fast” will cost is unknown. The thing to watch is Zhipu’s official announcement — if Highspeed turns out to be Omen Alpha, the “stealth model becomes the shipping one” script gains another data point.
How to try it
Update Zcode to 3.15.1 and look for GLM-5.3-Highspeed in the model list; if it isn’t there, you haven’t been picked in this round. If you have it, run a long-output task and read the live tok/s off the status bar — for now that’s the only way anyone can check the 490 figure.