Paper rebuilds tokenization with counting and global min-cost encoding, claiming up to 67% better compression than BPE
An arXiv paper proposes CNF-MCE tokenization: 26.7% better compression than o200k_base at 250K vocab, 67.0% at a million, downstream on par.
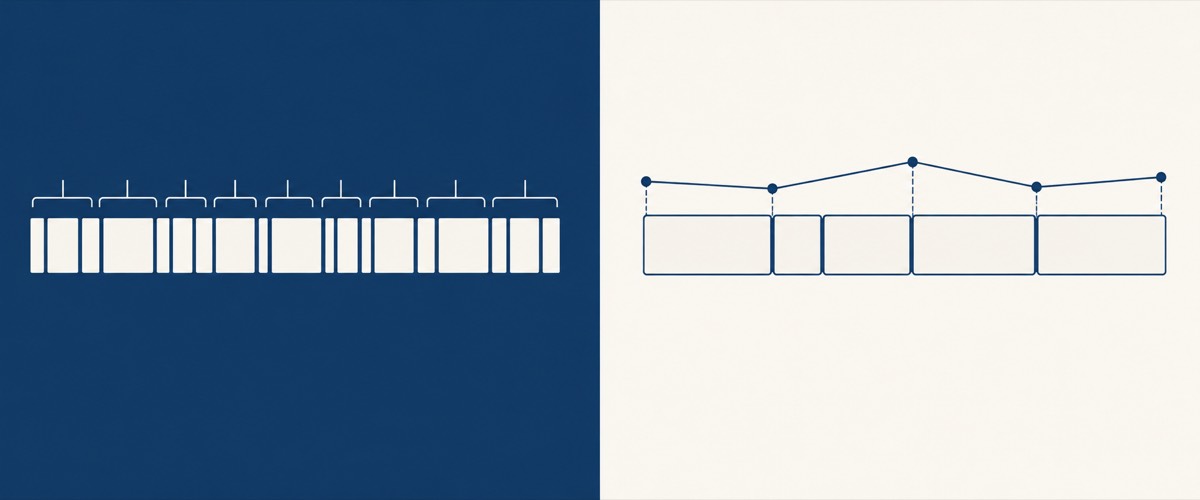
A paper submitted to arXiv on 1 October 2026, “Counting and Min-Cost Encoding for Tokenization in Large Language Models” (arXiv:2610.01127, ten authors including Shuming Shi and Ning Jiang), proposes a tokenization framework called CNF-MCE. Instead of building vocabularies and segmenting text through BPE’s bottom-up merges, it counts candidate substrings directly, filters the vocabulary by actual usage, and encodes with dynamic programming that finds the globally cheapest segmentation. On English web text at a 250K vocabulary, character-level compression improves 26.7% over o200k_base and 32.4% over qwen250k; at roughly a million entries the paper reports 67.0%.
Key points
- Submitted 1 October 2026 (cs.CL), the method decouples vocabulary construction from encoding: CNF handles “count candidates, then filter by usage” while MCE handles “find the lowest-cost segmentation over the whole text.”
- In the 250K group, CNF-MCE leads the evaluated BPE baselines across all six text categories (English web, PDF, math, code, Chinese and multilingual); English web CPT improves 20.6% over ds128k and 23.2% over qwen152k.
- Models trained from scratch at 1.8B and 8B parameters show “comparable average performance” to BPE-tokenizer models across 11 benchmarks — the claimed gain is compression, not downstream quality.
Background
The mainstream efficiency narrative is making each token cheaper to compute: better attention, KV-cache compression, quantized inference — a line that now includes Microsoft putting its Maia 300 inference chip into production (see Microsoft unveils Maia 300). All of it holds the token sequence length fixed. CNF-MCE attacks the other end — encoding the same text as fewer tokens, so inference time falls proportionally. InfoQ’s 14 October coverage frames it that way, and points at two structural BPE limits it targets: merge-history constraints (intermediate tokens occupying vocabulary capacity) and pre-tokenization boundaries that keep phrases like “the United States” from becoming a single token.
The facts
The paper’s reported numbers (all self-reported, as relayed by InfoQ):
| Metric | Value | Condition |
|---|---|---|
| English web compression gain | 26.7% / 32.4% | 250K vocabulary, vs o200k_base / qwen250k (character-level) |
| English web CPT gain | 20.6% / 23.2% | smaller-size group, vs ds128k / qwen152k |
| Million-entry vocabulary | 67.0% | English web, ~1M entries |
| Vocabulary utilization | 52.9% → 96.9% | in the 1K-to-1M scaling experiment |
| Downstream performance | on par | 1.8B and 8B trained from scratch, 11-benchmark average |
On the engineering side, CNF counts in rounds by candidate length and stops invalid extensions early using known prefix frequencies; the paper reports that building the raw vocabulary for a million English documents took under an hour on 32 threads. Mixed-vocabulary training used 6.9 million documents, building a 5-million-entry raw vocabulary before filtering to roughly 138K and 250K. MCE encodes over UTF-8 byte sequences with all 256 single-byte tokens in the vocabulary, so every input has a valid encoding path.
What others say
The paper’s own examples show the segmentation difference: with the same qwen250k vocabulary, BPE splits “pysimplesoap” into five tokens where MCE gets three; for “memory_efficient” both use the same count, but MCE isolates the underscore and keeps both words whole. InfoQ’s coverage also flags that compression and CPT are different metrics — a 32.4% CPT gain on English web text works out to roughly 24.5% fewer tokens, and “actual latency and cost still depend on the model and deployment configuration.”
The evidence boundary matters: this is a v1 preprint submitted on 1 October, the arXiv page carries only the abstract, and no third-party replication exists. The paper provides no code or data links, so the compression and downstream figures are the authors’ own.
Our take
For anyone optimizing inference cost, the paper’s value is putting tokenization back on the table as a variable — the vocabulary has long been treated as a BPE artifact, and CNF-MCE shows vocabulary construction and the encoding algorithm can be studied and replaced separately. Two gates stand between it and practice: there is no open-source implementation yet, so numbers like “vocabulary utilization from 52.9% to 96.9%” can only be taken on the author’s word; and the gains concentrate in compression while downstream quality is merely on par — whether the compute saved on tokens outweighs the migration cost (vocabulary, embeddings, and every existing model invalidated) is a calculation each team has to run.
The signal to watch next is whether code and data ship, and whether an independent team reproduces the compression numbers.